DeepSeek V4.1 is now the recommended model in EBITDAI
DeepSeek V4.1-Flash is live in EBITDAI, and it is now the first model we point people to for Excel work. It is the fastest model in the picker, it matches or beats Kimi k3 and Gemini 3.8 Flash on the benchmarks that look most like a modeling session, and it costs a fraction of both. It rides the plan you already have: nothing about the $15/month Pro tier changed.
What changed
DeepSeek shipped V4.1-Flash and retired the older V4-Flash. The company says V4.1 Flash "comprehensively surpassed V4 Pro in performance, cost, speed, and total time," and it is consolidating the line behind the new model: from September 14, 2026, requests to deepseek-v4-pro route to V4.1-Flash and bill at the Flash price.
In EBITDAI the model named DeepSeek now serves V4.1-Flash. There is nothing to reinstall and nothing to reconnect. If you were already running DeepSeek on one of the plans that carry it, your next build already runs on V4.1.
The benchmarks
The table below is DeepSeek's own V4.1 evaluation, released with the model. Read the rows that map to what an Excel agent actually does: long-horizon multi-step work, tool use, and verifiable code-style execution. Those are the columns where a spreadsheet agent lives or dies.
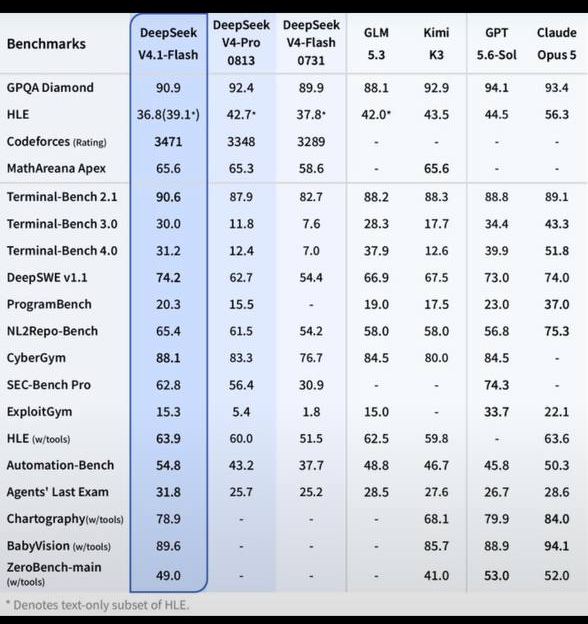
On Terminal-Bench 2.1, V4.1-Flash scores 90.6, ahead of Kimi K3 at 88.3 and Claude Opus 5 at 89.1. On the harder Terminal-Bench 3.0 and 4.0 it is roughly double Kimi K3 (30.0 against 17.7, and 31.2 against 12.6). It takes DeepSWE v1.1 at 74.2, its predecessor V4-Pro at 62.7 and Kimi K3 at 67.5. It leads NL2Repo-Bench (65.4), Automation-Bench (54.8), Agents' Last Exam (31.8), HLE with tools (63.9), Chartography with tools (78.9), BabyVision with tools (89.6) and ZeroBench-main (49.0), and sets a Codeforces rating of 3471, the highest in the table.
Kimi K3 is not swept. It keeps a small edge on pure reasoning, leading GPQA Diamond 92.9 to 90.9 and text-only HLE 43.5 to 39.1. For a chat benchmark that matters. For an agent wired into a workbook, where every step is a tool call against live cells, the tool-use and execution rows are the ones that decide whether your model ties out at the bottom, and V4.1-Flash wins most of them. It also beats the more expensive V4-Pro on nearly every row.
Speed, measured on our relay
Speed matters more in Excel than in a chat window, because a single model build is dozens of sequential steps and the latency compounds. On EBITDAI's relay this week, V4.1-Flash is the quickest of the three for modeling steps. DeepSeek publishes sustained throughput around 300 to 355 tokens per second, with peaks above 500, several times the older V4-Pro, and the Flash endpoint carries a concurrency limit of 2,500 against Pro's 500, so it holds that speed when the queue is long.
Kimi k3 has been the slowest and the most load-sensitive of the three, and Moonshot's endpoints stall under peak demand. Gemini 3.8 Flash is close to V4.1-Flash on raw decode, but a model build finishes sooner on V4.1-Flash because it spends fewer tokens thinking between steps. Those are our numbers, from our relay, on one week. They are not a universal claim about the models, and they move with provider load. What they explain is why DeepSeek is now the model we reach for first.
What the tokens cost
List prices per 1M tokens, pay-as-you-go, the rates you pay in own-key mode:
| Model | Input | Cached input | Output |
|---|---|---|---|
| DeepSeek V4.1-Flash | $0.15 | $0.003 | $0.60 |
| Gemini 3.8 Flash | $0.75 | $0.075 | $3.75 |
| Kimi k3, Moonshot pay-as-you-go | $3.00 | $0.30 | $15.00 |
DeepSeek rates shown are off-peak and double at peak, which is 01:00 to 04:00 and 06:00 to 10:00 UTC, Monday to Friday. Gemini pricing is introductory through December 31, 2026; from January 1, 2027 it is $1.50 input, $0.15 cached and $7.50 output. Kimi Code, the flat subscription you buy from Moonshot, carries no per-token charge at all.
The spread is the story. Output on V4.1-Flash is about a quarter the price of Gemini 3.8 Flash and a twenty-fifth the price of Kimi k3. Cached input, the rate that dominates the agent loop, is $0.003 on V4.1-Flash against $0.075 on Gemini and $0.30 on Kimi. And because most of the day is off-peak, the effective rate is often half the numbers above.
Put it in model builds. On our published hard suite, a complete build runs about $0.024 on V4.1-Flash, against $0.11 on Kimi k3 and $0.19 on Gemini 3.8 Flash. A $10 DeepSeek top-up covers a few hundred builds, and most users never come close to spending it in a month.
What it means for your plan
Nothing about the line-up moved. Pro is still $15/month ($144/year) and still runs every model on one shared monthly allowance, now with V4.1-Flash as the default pick: Kimi k3, DeepSeek V4.1 Flash, DeepSeek V4 Pro, Gemini 3.8 Flash, Meta Muse Spark 1.3 in both tiers, plus your own API keys for the providers and the QuickBooks, Campfire and Stripe connectors. The included usage each month, 7.5x what Lite carries, is yours to spend across any of them, and you switch models mid-session without losing your place. Lite is $5/month with 100x more usage than free, on Meta Muse Spark 1.3 Contributor.
Our recommendation is simple. Start on V4.1-Flash for everyday builds, because it is the fastest and it costs the least. Reach for Kimi k3 when you want its doctrine-faithful narration and notes, Gemini 3.8 Flash when you need a US-hosted model, and Meta Muse Spark 1.3 when you want the absolute cheapest task. In own-key mode you paste a DeepSeek key and your calls go straight from the add-in to DeepSeek, with zero markup from us.
Start today
V4.1-Flash is live on every plan right now. If you are already on Pro, open the picker and select DeepSeek. If you are not on a plan yet, Pro is $15/month and carries all of them. The DeepSeek in Excel guide walks through the key setup, and the API key tutorial covers the rest.
Related Articles
Gemini 3.8 Flash Is Live in EBITDAI Pro
Google's newest Flash model, plus Kimi k3 and DeepSeek V4.1 Flash, on the $15/month Pro plan.
Read moreHow to Use DeepSeek in Excel
No waitlist, cents per model build: connect a DeepSeek key in five minutes.
Read moreEBITDAI Is Now Powered by Kimi and DeepSeek
AI usage included on every paid plan, or bring your own AI account: same CFO-grade models.
Read more